model: "gpt-5.6-sol"Extraction
Extract the renewal date and total contract value from this agreement…
Choose better. Spend smarter.
Benchmark your workload across 150+ models, or route requests through one API with Grid or Wire.
How it works
Run your actual AI requests across 150+ models. Elektric independently evaluates the responses for quality, cost, and relevant supporting metrics.
Your requests are run across 150+ models and independently evaluated for quality, cost, and relevant supporting metrics.
Elektric analyzes 1,000 requests or 7 days of traffic, whichever comes first, and tests each request across every model.
model: "gpt-5.6-sol"Extract the renewal date and total contract value from this agreement…
Each model answers your request. Elektric independently scores response quality and measures the cost.
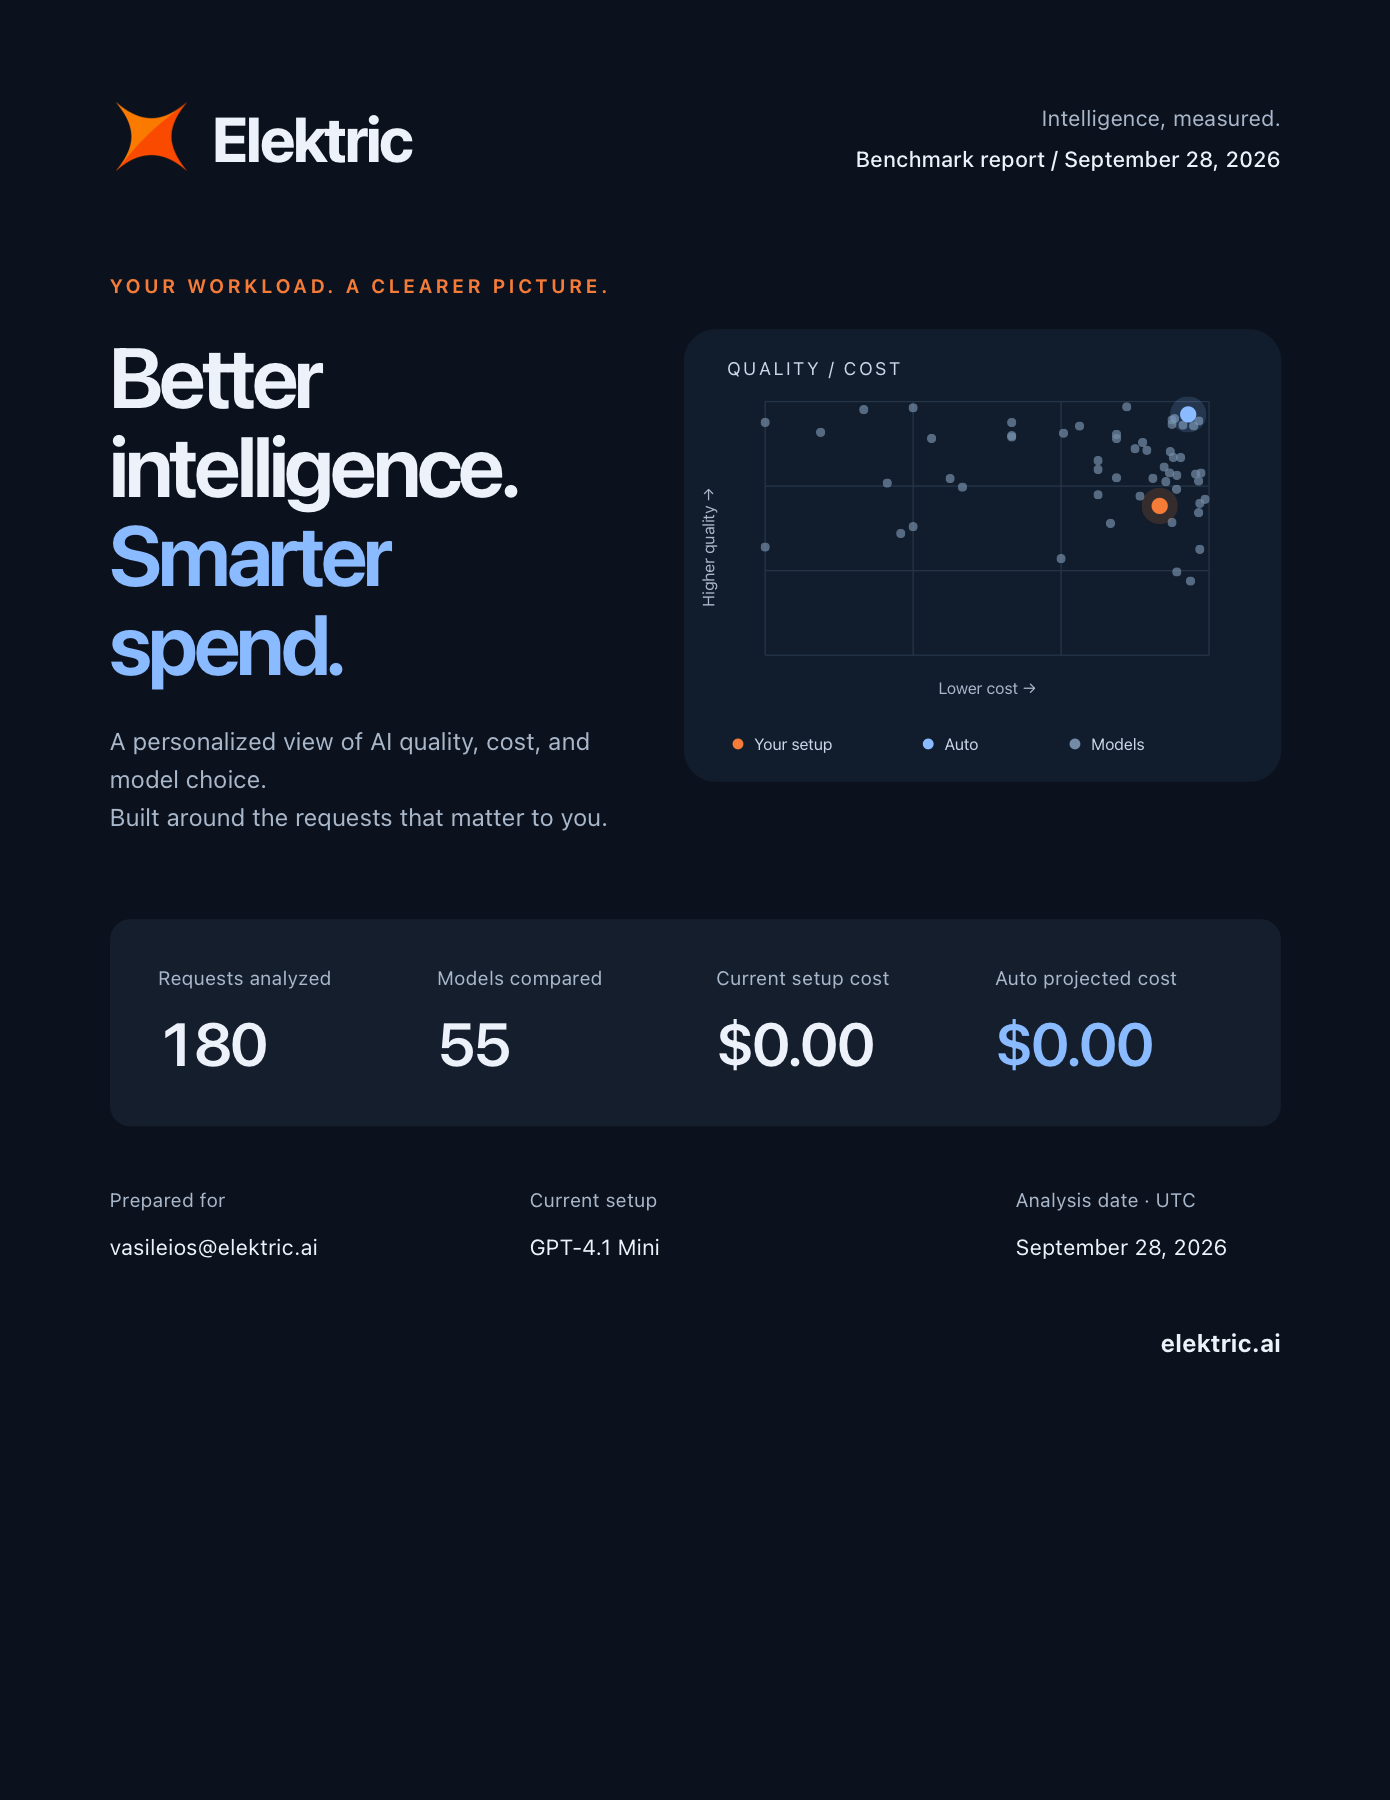
Compare all models by quality and cost, see where your current setup lands, and find a better fit.
Illustrative comparison, not measured performance.
Start saving with Elektric Grid now, or put what you learned to work with Elektric Wire.
Explore Routing